Building a Regression MLP Using the Sequential API
Let’s switch to the California housing problem and tackle it using a regression neural network. For simplicity, we will use Scikit-Learn’s fetch_california_housing() function to load the data. This dataset is simpler since it contains only numerical features. There is no ocean_proximity feature, and there is no missing value. After loading the data, we split it … Read more

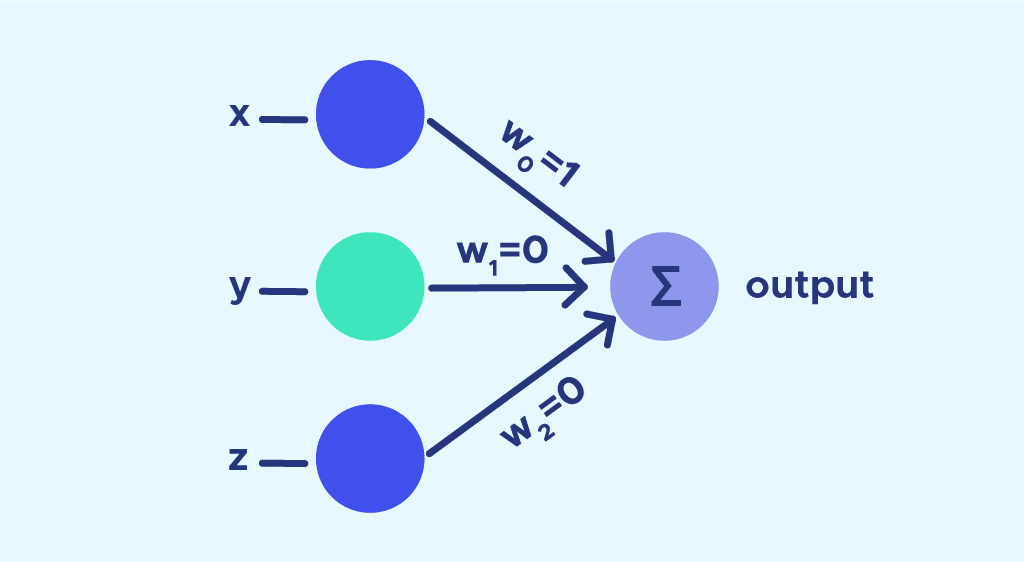
Logical Computations with Neurons | Deep learning

Warren McCulloch and Walter Pitts proposed a very simple model of the biological neuron, which later became known as an artificial neuron: it has one or more binary (on/off) inputs and one binary output. The artificial neuron simply activates its output when more than a certain number of its inputs are active. McCulloch and Pitts … Read more

What is Stochastic Gradient Descent?

Stochastic Gradient Descent (SGD) is an optimization algorithm commonly used in machine learning for training models, particularly in large-scale and online learning settings. It is an iterative optimization algorithm that aims to minimize a cost or loss function by adjusting the model parameters. Here’s an overview of how SGD works: Basic Concept: Advantages and Considerations: … Read more

How to Extract Code from a Screenshot with 100% Accuracy?

Did you like an image containing code & take its screenshot? Now you want to copy the code from that screenshot, right? Panic not, because I’ve got you covered. In this handy guide, I’ll provide you with some simple steps so that you can extract code from a screenshot efficiently. This guide is your go-to … Read more

Quintile Analysis: Bringing it all togetherand making decisions

Introduction Quintile analysis is a statistical method used to divide a data set into five equal parts, each representing 20% of the total observations. This method is often used in finance, economics, and sociology to analyze distributions, rankings, or performance. Quintile Analysis: with random data Quintile analysis is a common framework for evaluating the efficacy … Read more

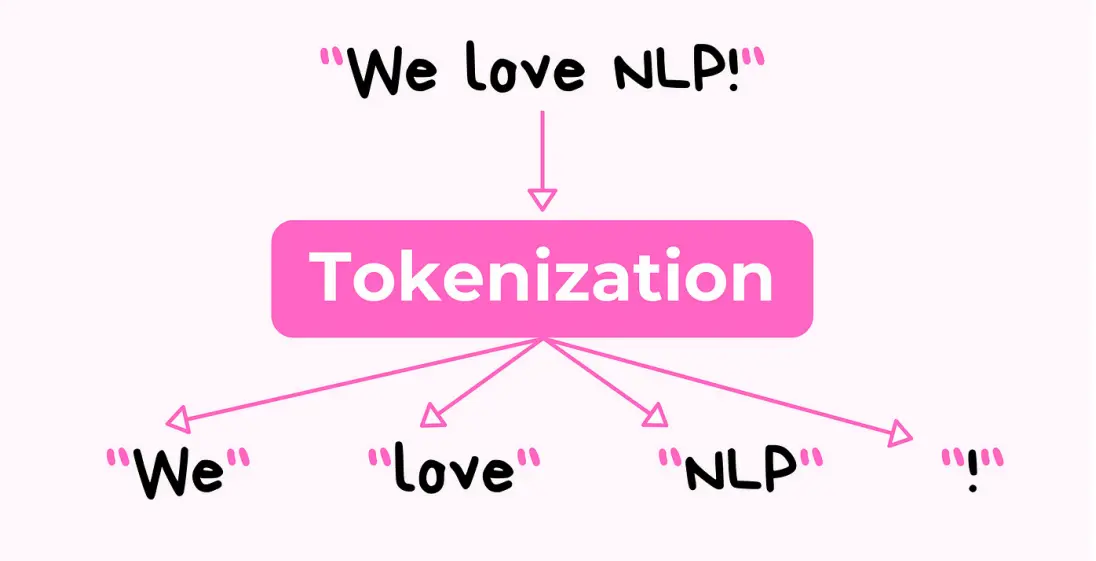
Tokenization in NLP

Word Level Tokenzation Splitting text into individual words “the quick brown fox” -> [“the”,”quick”,”brown”,”fox”] BUT Character Level Tokenization Splitting text into individual characters “the quick brown fox” -> [“t”,”h”,”e”,” “,”q”,”u”,”i”,”c”,”k”, …] But N-GRAM MODELS Splitting text into groups of consecutive words. N is the no. of words in a token. For a trigram model, “the … Read more

What is Exploratory Data Analysis (EDA)?

Exploratory Data Analysis

Exploratory Data Analysis (EDA) is an essential step in any data science project. It involves investigating and analyzing datasets to understand their characteristics, identify patterns, detect outliers, and uncover relationships between variables. EDA helps in gaining initial insights into the data before diving into more complex analyses. The Foremost Goals of EDA Types of EDA … Read more

Anomaly Detection using Gaussian Mixtures

Introduction Anomaly detection (also called outlier detection) is the task of detecting instances that deviate strongly from the norm. These instances are of course called anomalies or outliers, while the normal instances are called inliers. Anomaly detection is very useful in a wide variety of applications, for example in fraud detection, or for detecting defective … Read more

A Journey From Biological to Artificial Neurons

Surprisingly, ANNs have been around for quite a while: they were first introduced back in 1943 by the neurophysiologist Warren McCulloch and the mathematician Walter Pitts. In their landmark paper, “A Logical Calculus of Ideas Immanent in Nervous Activity,”. McCulloch and Pitts presented a simplified computational model of how biological neurons might work together in … Read more

Bayesian Gaussian Mixture Models

Rather than manually searching for the optimal number of clusters, it is possible to use instead the BayesianGaussianMixture class which is capable of giving weights equal (or close) to zero to unnecessary clusters. Just set the number of clusters n_components to a value that you have good reason to believe is greater than the optimal … Read more

Understanding DBSCAN Clustering Algorithm: Implementation in Python

Before we move on to Gaussian mixture models, let’s take a look at DBSCAN, another popular clustering algorithm that illustrates a very different approach based on local density estimation. This approach allows the algorithm to identify clusters of arbitrary shapes. Understanding DBSCAN Clustering Algorithm DBSCAN (Density-Based Spatial Clustering of Applications with Noise) is a popular … Read more

Using Clustering for Semi-Supervised Learning

Another use case for clustering is in semi-supervised learning, when we have plenty of unlabeled instances and very few labeled instances. Let’s train a logistic regression model on a sample of 50 labeled instances from the digits dataset: n_labeled = 50 log_reg = LogisticRegression() log_reg.fit(X_train[:n_labeled], y_train[:n_labeled]) What is the performance of this model on the … Read more

Using clustering for image segmentation

Image segmentation is the task of partitioning an image into multiple segments. In semantic segmentation, all pixels that are part of the same object type get assigned to the same segment. For example, in a self-driving car’s vision system, all pixels that are part of a pedestrian’s image might be assigned to the “pedestrian” segment … Read more

Accelerated K-Means and Mini-batch K-Means

Introduction Another important improvement to the K-Means algorithm was proposed in a 2003 paper by Charles Elkan. It considerably accelerates the algorithm by avoiding many unnecessary distance calculations: this is achieved by exploiting the triangle inequality (i.e., the straight line is always the shortest) and by keeping track of lower and upper bounds for distances … Read more

Implementation of K-Means Clustering in Machine Learning

Consider the unlabeled dataset represented in Figure below: you can clearly see 5 blobs of instances. The K-Means algorithm is a simple algorithm capable of clustering this kind of dataset very quickly and efficiently, often in just a few iterations. It was proposed by Stuart Lloyd at the Bell Labs in 1957 as a technique … Read more

What is Stacking of Models in Machine Learning?

The last Ensemble method we will discuss in this series is called stacking (short for stacked generalization). It is based on a simple idea: instead of using trivial functions (such as hard voting) to aggregate the predictions of all predictors in an ensemble, why don’t we train a model to perform this aggregation? Figure below … Read more