Implementing Ridge Regression from Scratch

For Linear Regression in Machine learning with two variables we have to find 2 coefficient. In case of overfitting these 2 coefficients can be very high. Y=mX+c So to handle this, Idea is that we want to reduce the value of coefficient(m). By doing this biasness can increase but variance decreases. Which is called bias … Read more
Titanic – Advanced Feature Engineering Tutorial

Introduction I decided to write this kernel because Titanic: Machine Learning from Disaster is one of my favorite competitions on Kaggle. This is a beginner level kernel which focuses on Exploratory Data Analysis and Feature Engineering. A lot of people start Kaggle with this competition and they get lost in extremely long tutorial kernels. This is a short kernel compared … Read more

Feature Engineering in Machine Learning

feature engineering Cover Pic

Introduction Feature engineering, often hailed as the cornerstone of machine learning, holds the power to transform raw data into actionable insights. In the realm of predictive modeling, where the quality of features can significantly influence model performance, mastering the art of feature engineering is indispensable. In this comprehensive guide, we’ll embark on a Titanic journey … Read more

Gaussian Mixtures Models in Machine Learning

A Gaussian mixture model (GMM) is a probabilistic model that assumes that the instances were generated from a mixture of several Gaussian distributions whose parameters are unknown. All the instances generated from a single Gaussian distribution form a cluster that typically looks like an ellipsoid. Each cluster can have a different ellipsoidal shape, size, density … Read more

Kernel PCA in Machine Learning

The post discusses Kernel Principal Component Analysis (kPCA), highlighting its application in nonlinear dimensionality reduction and suggesting methods for selecting kernels and tuning hyperparameters through grid search and reconstruction pre-image error minimization.

Hierarchical Clustering in Machine Learning

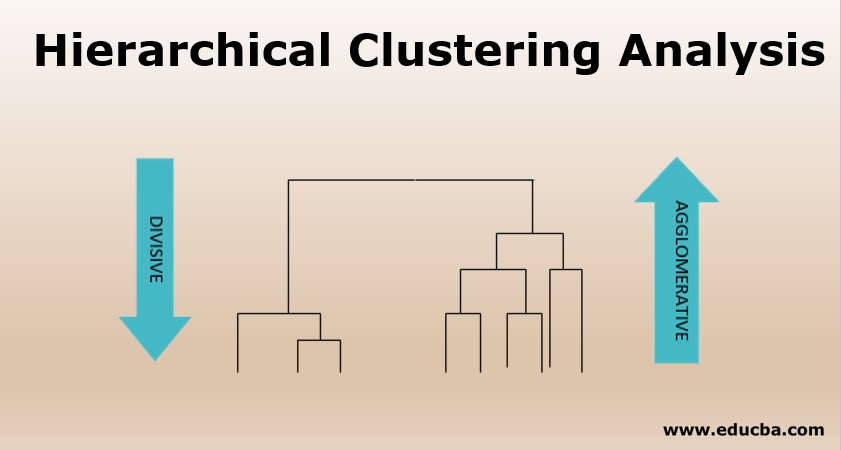
Hierarchical-Clustering-Analysis.

The content discusses K-Means and Hierarchical Clustering algorithms. K-Means requires predefined clusters and is sensitive to initial centroids and outliers. Hierarchical Clustering offers an agglomerative and divisive approach without preset clusters. The document also explores various linkage methods, dendrograms for visualization, and the validity of clusters over time.

Choosing the Right Number of Dimensions in Dimensionality Reduction

The content discusses dimensionality reduction using PCA, emphasizing the importance of preserving a significant portion of variance, typically 95%. It explains how to compute PCA, options for variance preservation, and the benefits of compression on datasets like MNIST. Additionally, it introduces Randomized PCA and Incremental PCA for efficiency in handling large datasets.

Dimensionality Reduction in Machine Learning: PCA, Projection & Manifold Learning

This content discusses dimensionality reduction approaches, focusing on projection and Manifold Learning. It explains how projection simplifies high-dimensional data, exemplified by datasets like the Swiss roll. Principal Component Analysis (PCA) is highlighted as a key algorithm for preserving variance while reducing dimensions, with SVD as a method for determining principal components.

Introduction to Dimensionality Reduction

The text discusses the curse of dimensionality in machine learning, highlighting challenges in high-dimensional spaces. It suggests reducing features to improve training efficiency and visualization, while addressing potential information loss and risks of overfitting with increased dimensions. Dimensionality reduction techniques will be explored further.

Gradient Boosting in Machine Learning

Another very popular Boosting algorithm is Gradient Boosting. Just like AdaBoost,Gradient Boosting works by sequentially adding predictors to an ensemble, each one correcting its predecessor. However, instead of tweaking the instance weights at every iteration like AdaBoost does, this method tries to fit the new predictor to the residual errors made by the previous predictor. … Read more

Boosting( Ensemble) Trees | Machine Learning from Scratch

Introduction Boosting (originally called hypothesis boosting) refers to any Ensemble method that can combine several weak learners into a strong learner. The general idea of most boosting methods is to train predictors sequentially, each trying to correct its predecessor. There are many boosting methods available, but by far the most popular are AdaBoost13 (short for … Read more

Sending Data in Unstructured File Form

Unstructured data files consist of a series of bits. The file doesn’t separate the bits from each other in any way. You can’t simply look into the file and see any structure because there isn’t any to see. Unstructured file formats rely on the file user to know how to interpret the data. For example, … Read more

Random Forests | Machine Learning from Scratch

As we have discussed, a Random Forest is an ensemble of Decision Trees, generally trained via the bagging method (or sometimes pasting), typically with max_samples set to the size of the training set. Instead of building a BaggingClassifier and passing it a DecisionTreeClassifier, you can instead use the RandomForestClassifier class, which is more convenient and … Read more

Uploading, Streaming, and Sampling Data Using Python

Introduction Storing data in local computer memory represents the fastest and most reliable means to access it. The data could reside anywhere. However, you don’t actually interact with the data in its storage location. You load the data into memory from the storage location and then interact with it in memory. Uploading small amounts of … Read more

What is Artificial Neural Network (ANN)?

A. Introduction to neural networksB. ANN architectures C. Learning methods D. Learning rule on supervised learning E. Feedforward neural network with Gradient descent optimization Introduction to neural networks Definition: the ability to learn, memorize and still generalize, prompted research in algorithmic modeling of biological neural systems. Human brain has the ability to perform tasks such … Read more

What is Bagging and Pasting? Machine Learning from Scratch

Introduction One way to get a diverse set of classifiers is to use very different training algorithms, as just discussed. Another approach is to use the same training algorithm for every predictor, but to train them on different random subsets of the training set. When sampling is performed with replacement, this method is called bagging … Read more

What is Ensemble Learning? | Machine Learning from Scratch

Introduction: Welcome to our comprehensive tutorial on Ensemble Learning! In this guide, we’ll delve into the fascinating world of Ensemble methods, exploring how they harness the collective intelligence of multiple models to achieve superior performance in machine learning tasks. Whether you’re a seasoned practitioner or just stepping into the realm of machine learning, understanding Ensemble … Read more

Decision Tree Regression | Machine Learning from Scratch

Decision Trees are also capable of performing regression tasks. Let’s build a regression tree using Scikit-Learn’s DecisionTreeRegressor class, training it on a noisy quadratic dataset with max_depth=2: from sklearn.tree import DecisionTreeRegressor tree_reg = DecisionTreeRegressor(max_depth=2) tree_reg.fit(X, y) The resulting tree is represented below This tree looks very similar to the classification tree you built earlier. The … Read more

Gini Impurity or Entropy? How to decide the root node in decision tree?

By default, the Gini impurity measure is used, but you can select the entropy impurity measure instead by setting the criterion hyperparameter to “entropy”. The concept of entropy originated in thermodynamics as a measure of molecular disorder: entropy approaches zero when molecules are still and well ordered. It later spread to a wide variety of … Read more